


 |
市場調查報告書
商品編碼
2099836
GDDR7 市佔率分析(適用於 AI 推理 GPU)、產業趨勢與統計及成長預測(2026-2031 年)GDDR7 For AI Inference GPU - Market Share Analysis, Industry Trends & Statistics, Growth Forecasts (2026 - 2031) |
||||||

※ 本網頁內容可能與最新版本有所差異。詳細情況請與我們聯繫。
據 Mordor Intelligence 稱,用於 AI 推理 GPU 的 GDDR7 市場規模預計將從 2025 年的 5.8 億美元成長到 2026 年的 8.9 億美元,到 2031 年達到 50.3 億美元,預計 2026 年至 2031 年的複合年成長率為 41.4%。
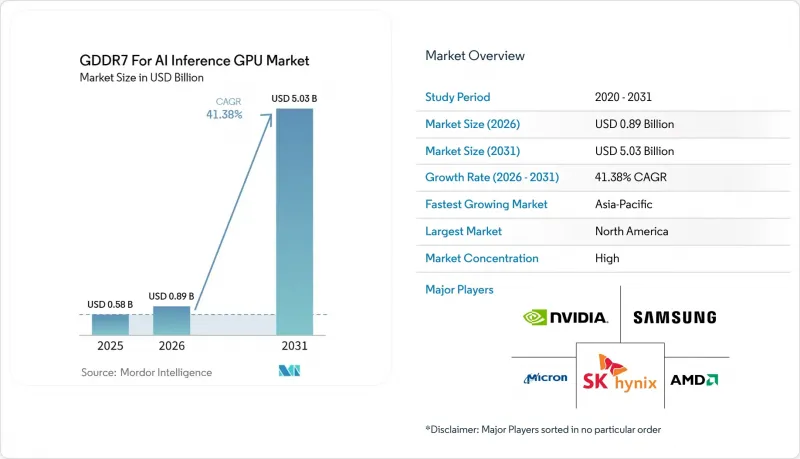
本報告按內存容量(16 Gb、24 Gb、32 Gb 及以上)、內存數據速率(最高 32 Gbps、32 Gbps 及以上)、應用領域(資料中心 AI 推理、邊緣 AI 推理、工作站 AI 等)、終端用戶行業(雲端和超大規模資料中心、OEM 工作站、政府和國防等)以及地區進行細分。市場預測以美元 (USD) 為單位。
GDDR7在AI推理GPU中的全球趨勢與洞察
提高 GDDR7 平台上的 AI 推理吞吐量
用於人工智慧推理GPU的GDDR7市場正在擴張。這是因為在實際運作環境中,記憶體頻寬是令牌產生和回應速度的直接阻礙因素。 JEDEC GDDR7標準設定了高達32 Gbps的初始資料傳輸速率,並制定了向48 Gbps邁進的藍圖,與上一代產品相比,資料吞吐量顯著提升。 Lambuth也指出,GDDR7單晶片吞吐量最高可達192 GB/s,而GDDR6僅96 GB/s。這意味著無需完全遷移到更昂貴的記憶體架構即可提高吞吐量。這對推理伺服器至關重要,因為更高的頻寬可以減少達到目標效能等級所需的記憶體設備數量,從而降低基板複雜性並有助於更好地控制成本。這項優勢在工作站和一體機等應用場景中也同樣重要,因為與大規模訓練叢集相比,這些場景的功耗、散熱和基板空間限制更為嚴格。隨著推理任務從研究環境轉移到商業系統,AI 推理 GPU 的 GDDR7 市場受益於速度、成本和系統簡易性之間的實際平衡。
透過 PAM3 訊號傳輸實現節能頻寬擴展
GDDR7 內存在 AI 推理 GPU 市場的驅動力之一在於其能源效率的提升,這在資料中心和邊緣系統對功率密度限制日益嚴格的今天顯得尤為重要。 Lambuth 解釋說,與傳統訊號方式相比,PAM3 訊號將每個時脈週期的資料傳輸提高了 50%,從而在無需大幅提升時脈頻率的情況下提高了有效資料速率。三星表示,其 24GB GDDR7 記憶體採用時脈控制管理和雙 VDD 結構,與上一代產品相比,耗電量降低了 30% 以上。美光也將 GDDR7 定位為適用於混合 CPU、GPU 和 NPU 系統的低延遲、高能源效率 AI 工作流程平台。這種高能效正在拓展 GDDR7 內存在 AI 推理 GPU 市場的應用範圍,使其從主流雲端硬體擴展到工業設備、通訊邊緣系統和設備內 AI 平台。此外,由於買家不僅會比較尖峰時段訓練性能,還會考慮推理的經濟性,因此 GDDR7 也為供應商提供了更強的賣點。
大規模人工智慧訓練中的 HBM 偏好
GDDR7 記憶體對 AI 推理 GPU 市場的最大限制在於,大規模 AI 訓練系統仍偏好 HBM 顯存。在訓練叢集,最大化每個加速器的頻寬仍然是首要任務,這使得 HBM3e 和 HBM4 在預算充足的運算環境中更具吸引力。儘管 GDDR7 記憶體非常適合 AI 推理,但這限制了 AI 推理 GPU 市場滲透到超大規模運算領域頂端的程度。負責人對這項技術的熟悉程度是另一個障礙,因為採購團隊通常會將訓練時代的基準測試和認證要求應用於推理硬體。這減緩了那些已經採用 HBM 平台和廠商標準技術的客戶的採用速度。因此,雖然需求不會崩壞,但進入 AI 硬體生命週期中以訓練主導的高階細分市場將存在上限。
細分市場分析
到2025年,16GB顯存容量的GDDR7顯存將佔AI推理GPU市場佔有率的63.8%。這反映了基於Blackwell架構的部署浪潮的初期發展,以及早期產品發布中16GB顯存產品的廣泛普及。鑑於企業和雲端平台的更新周期並非一年之內完成,此部署基礎確保了16GB顯存將持續佔據市場主導地位。許多買家仍然選擇這一容量級別,因為它在當前平台上實現了吞吐量、成本和可用性之間的務實平衡。預計到2031年,32GB及以上容量的GDDR7顯存將以44.6%的複合年成長率成長,成為AI推理GPU GDDR7市場中成長最快的容量等級。這一成長反映了隨著推理作業擴大處理更長的上下文視窗、多模態輸入以及更多的本地模型託管,對更大顯存容量的需求日益成長。
24GB 容量段處於中間位置,在無需徹底重新設計記憶體子系統的情況下,顯著提升單通道容量,發揮至關重要的作用。 2024 年,三星宣布其 24GB GDDR7 記憶體專為下一代 AI 運算而設計,兼顧了高密度和更高的能源效率。這使得 24GB 成為那些需要 16GB 記憶體容量不足的額外記憶體空間,但又希望成本逐步增加,避免超高密度配置帶來的價格飆升的廠商的理想選擇。未來,雖然 16GB 記憶體仍將在 AI 推理 GPU 的 GDDR7 市場中佔據重要的出貨量,但 24GB 和 32GB 以上容量預計將逐漸成為高階推理硬體的上限。從實際應用角度來看,記憶體密度不再只是一個規格參數;重點正在轉移到模型能否駐留在本地顯存 (VRAM) 中,而無需將資料推送到速度較慢的系統記憶體。
到2025年,「最高32Gbps」的GDDR7顯存將佔AI推理GPU市場81.1%的佔有率,這表明該市場在早期階段已趨於成熟,且用戶更傾向於易於獲取的速度範圍。該細分市場擁有廣泛的供應商支持,並與現有基板設計高度相容,從而減輕了GPU製造商的認證負擔。此外,它還能滿足主流推理應用場景的需求,這些場景需要高吞吐量,但對效能要求並非極高。 「超過32Gbps」的GDDR7顯存市場預計到2031年將以43.9%的複合年成長率成長,反映出市場對大規模情境處理、即時多模態模態處理以及更苛刻的視覺AI工作負載的需求不斷成長。隨著系統設計人員追求更高的單板效能,速度正成為AI推理GPU GDDR7市場中日益重要的差異化因素。
向更高速度等級的過渡不僅關乎記憶體晶片;隨著速度的提升,對基板材料、佈線精度和散熱設計的要求也隨之提高。 JEDEC 於 2024 年 3 月最終確定了 GDDR7互通性框架,允許供應商在通用標準結構內擴展不同速度等級的產品。這種標準化降低了對單一供應商的依賴,並為未來的產品路線圖制定了更明確的藍圖。儘管如此,對於 AI 推理 GPU 行業的 GDDR7 而言,預計短期內大部分出貨量仍將保持在「最高 32 Gbps」的範圍內,而速度更快的等級將繼續集中用於高階設備和高階加速器的設計。因此,市場將出現一種兩極化的格局:成熟的速度等級支持大規模生產擴張,而速度更快的等級將塑造未來的性能主導。
區域分析
預計到2025年,北美將佔據AI推理GPU GDDR7市場45.9%的佔有率,成為最大的區域貢獻者。該地區受益於超大規模雲端服務供應商、AI晶片設計商和企業硬體採購商在美國的集中。此外,能夠快速將新型推理基礎設施商業化的平台提供者也為該地區提供了強勁動力。 2026年1月,AWS宣布推出EC2 G7e,將基於GDDR7的推理功能引入廣泛的企業雲端服務。此外,該地區對產品藍圖的發展也具有顯著影響,因為GPU架構師、雲端公司和企業軟體堆疊的許多系統級決策都是在北美做出的。
歐洲在採用GDDR7顯存的GPU人工智慧推理市場中佔據著雖小但穩定的佔有率,這得益於企業人工智慧的普及、工業自動化以及公共部門對更可控運算環境的需求。該地區非常適合部署對隱私、資料處理和本地控制要求極高的工作站和設備。國防領域的需求也日益顯著,尤其是在穩健型嵌入式運算應用方面。 Kontron將於2026年7月推出國防與航太領域的人工智慧推理GPU VX33211,反映了市場正向任務就緒型邊緣平台轉型。這些因素表明,歐洲市場的出貨量將呈現穩定成長的態勢,而非快速激增。
亞太地區是成長最快的地區,預計到2031年複合年成長率將達到43%,這主要得益於其主導的生產地位和不斷成長的終端用戶需求。三星和SK海力士佔據了該地區相當大的市場佔有率,而中國、日本、韓國和台灣在需求和一體化方面發揮著至關重要的作用。根據路透社報道,英偉達面向中國的「Blackwell」產品將採用GDDR7顯存而非HBM顯存,這表明政策和區域准入要求正在重塑亞洲的硬體設計。美光也在日本將GDDR7顯存應用於人工智慧PC和混合運算工作流程,顯示企業對GDDR7的需求正在超越雲端基礎設施的範疇。雖然「世界其他地區」目前的規模較小,但由於各國政府加大對人工智慧和雲端基礎設施的投資,其在預測期後半段的角色可能會擴大。
其他好處:
- Excel格式的市場預測(ME)表
- 3個月的分析師支持
目錄
第1章:引言
- 研究假設和市場定義
- 調查範圍
第2章:調查方法
第3章執行摘要
第4章 市場狀況
- 市場概覽
- 市場促進因素
- 在注重成本效益的部署環境中,提升 AI 推理吞吐量,超越 HBM。
- 利用 PAM3 訊號方案實現節能頻寬擴充。
- 在人工智慧工作站和邊緣伺服器中快速普及
- GDDR7在高階GPU發布週期中的採用記錄
- 24Gb 和 32Gb 晶片供應商認證進展
- 企業和政府人工智慧程式對本地化推理的需求
- 市場限制因素
- 在大規模訓練和頻寬密集型推理中選擇 HBM。
- 最先進DRAM的生產能力限制與分配原則
- 緊湊型加速器中的散熱和電路板級整合限制
- GPU、記憶體控制器和基板設計之間存在相容性摩擦。
- 產業價值鏈分析
- 監理情勢
- 技術展望
- 波特五力分析
- 宏觀經濟因素對市場的影響
第5章 市場規模與成長預測
- 按內存密度
- 16 Gb
- 24 Gb
- 32 GB 或更多
- 按記憶體資料傳輸速度
- 最高可達 32 Gbps
- 32 Gbps 或更高
- 透過使用
- 資料中心的人工智慧推理
- 邊緣人工智慧推理
- 工作站人工智慧
- 消費者人工智慧加速
- 按最終用戶行業分類
- 雲端和超大規模資料中心
- 企業IT
- OEM工作站
- 政府/國防
- 其他終端用戶產業
- 按地區
- 北美洲
- 歐洲
- 亞太地區
- 中國
- 日本
- 韓國
- 台灣
- 其他亞太國家
- 世界其他地區
第6章 競爭情勢
- 市場集中度
- 策略趨勢
- 市佔率分析
- 公司簡介
- Samsung Electronics Co., Ltd.
- SK hynix Inc.
- Micron Technology, Inc.
- NVIDIA Corporation
- Advanced Micro Devices, Inc.
- Rambus Inc.
- TSMC
- Intel Corporation
- Synopsys, Inc.
- Cadence Design Systems, Inc.
第7章 市場機會與未來展望
According to Mordor Intelligence, the GDDR7 for AI inference GPU market size is expected to increase from USD 0.58 billion in 2025 to USD 0.89 billion in 2026 and reach USD 5.03 billion by 2031, growing at a CAGR of 41.4% over 2026-2031.
This report is Segmented by Memory Density (16 Gb, 24 Gb, and 32 Gb and Above), Memory Data Rate (Up To 32 Gbps, and Above 32 Gbps), Application (Data Center AI Inference, Edge AI Inference, Workstation AI, and More), End-User Industry (Cloud and Hyperscale Data Centers, OEM Workstations, Government and Defense, and More), and Geography. The Market Forecasts are Provided in Terms of Value (USD).
Global GDDR7 For AI Inference GPU Market Trends and Insights
AI Inference Throughput Gains on GDDR7 Platforms
The GDDR7 for AI inference GPU market is moving higher because memory bandwidth has become a direct limiter for token generation and response speed in production inference. The JEDEC GDDR7 standard sets initial data rates up to 32 Gbps and defines a roadmap to 48 Gbps, which materially increases data throughput compared to the prior generation. Rambus also noted that GDDR7 can deliver up to 192 GB/s per device, compared with 96 GB/s for GDDR6, which improves throughput without forcing a full shift to more expensive memory architectures. This matters in inference servers because higher bandwidth can reduce the number of memory devices needed to achieve a target performance level, helping lower board complexity and improve cost discipline. The same advantage matters in workstation and appliance formats, where power, thermal limits, and board space are tighter than in large training clusters. As more inference tasks move into commercial systems rather than research environments, the GDDR7 for AI inference GPU market is gaining from this practical balance between speed, cost, and system simplicity.
Power-Efficient Bandwidth Scaling With PAM3 Signaling
The GDDR7 for AI inference GPU market is also being supported by better energy efficiency, which matters as power density limits tighten across data centers and edge systems. Rambus explained that PAM3 signaling carries 50% more data per clock cycle than prior signaling methods, thereby raising effective data rates without an equal increase in clock frequency. Samsung stated that its 24 GB GDDR7 used clock control management and a dual-VDD structure, cutting power draw by more than 30% compared to its predecessor. Micron has also positioned GDDR7 as a platform for lower-latency and more power-efficient AI workflows across hybrid CPU, GPU, and NPU systems. This efficiency profile helps the GDDR7 for AI inference GPU market extend beyond mainstream cloud hardware into industrial appliances, telecom edge systems, and on-device AI platforms. It also gives suppliers a stronger case when buyers compare inference economics rather than peak training performance alone.
HBM Preference in Large-Scale AI Training
The largest restraint on the GDDR7 for the AI inference GPU market is the continued preference for HBM in large-scale AI training systems. Training clusters still prioritize the highest possible bandwidth per accelerator, and that makes HBM3e and HBM4 more attractive for the most expensive compute budgets. This limits how far the GDDR7 for AI inference GPU market can penetrate the top tier of hyperscale spending, even when it is well-suited for inference. Buyer familiarity adds another barrier, because procurement teams often apply training-era benchmarks and qualification expectations to inference hardware. That slows adoption in accounts that already standardized around HBM-equipped platforms and vendor stacks. The result is not a collapse in demand, but a ceiling on participation in the most premium training-led portions of the AI hardware cycle.
Other drivers and restraints analyzed in the detailed report include:
- Rapid Adoption in AI Workstations and Enterprise Appliances
- GDDR7 Design Wins in Premium AI GPU Segments
- Limited Leading-Edge DRAM Capacity Amid HBM Competition
For complete list of drivers and restraints, kindly check the Table Of Contents.
Segment Analysis
The 16 GB segment held 63.8% of the GDDR7 for AI inference GPU market size in 2025, which reflected the first wave of Blackwell-based deployments and the wide availability of 16 GB parts across early product launches. This installed base gives 16 GB a durable role because enterprise and cloud refresh cycles do not turn over in a single year. Many buyers are still choosing this tier because it offers a practical balance between throughput, cost, and availability in current platforms. The 32 GB and Above segment is projected to grow at a 44.6% CAGR through 2031, making it the fastest-expanding density band in the GDDR7 for AI inference GPU market. That growth reflects rising demand for larger VRAM pools as inference jobs handle longer context windows, multimodal inputs, and more local model hosting.
The 24 GB segment sits in the middle and plays an important role, raising capacity per channel without requiring a full redesign of the memory subsystem. Samsung said in 2024 that its 24 Gb GDDR7 was built for next-generation AI computing and delivered both higher density and improved power efficiency. That makes 24 GB useful for vendors that need more memory headroom than 16 GB can offer but want a more measured cost step than very high-density configurations. Over time, the GDDR7 for AI inference GPU market is likely to see 16 Gb remain important for volume shipments while 24 Gb and 32 Gb and Above increasingly define the ceiling for premium inference hardware. In practical terms, density is becoming less about specification positioning and more about whether a model can stay resident in local VRAM without pushing data into slower system memory.
The Up to 32 Gbps segment captured 81.1% of the GDDR7 for AI inference GPU market in 2025, showing that the early market favored mature, more readily available speed bins. This tier benefits from broader supplier readiness and a better fit with current board designs, which lowers qualification friction for GPU makers. It also supports mainstream inference use cases that need strong throughput but do not require the most aggressive performance profile. The Above 32 Gbps segment is forecast to expand at a 43.9% CAGR through 2031, reflecting rising demand for larger context handling, real-time multimodal processing, and more demanding visual AI workloads. As system designers push for more performance per board, speed is becoming a stronger point of differentiation inside the GDDR7 for the AI inference GPU market.
The shift to faster tiers is not only a matter of memory silicon, because board materials, routing precision, and thermal design also become more demanding as speeds rise. JEDEC finalized the interoperability framework for GDDR7 in March 2024, which helps vendors scale across speed grades within a common standards structure. That standardization reduces single-supplier dependence and supports a clearer roadmap for future products. Even so, the GDDR7 for AI inference GPU industry will likely keep most near-term shipment volume in the Up to 32 Gbps band while faster bins remain concentrated in premium appliances and high-end accelerator designs. The result is a split structure where mature speed grades support volume growth and higher speed grades shape future performance leadership.
Complete Report Scope:
- By Memory Density
- 16 Gb
- 24 Gb
- 32 Gb and Above
- By Memory Data Rate
- Up To 32 Gbps
- Above 32 Gbps
- By Application
- Data Center AI Inference
- Edge AI Inference
- Workstation AI
- Consumer AI Acceleration
- By End-User Industry
- Cloud and Hyperscale Data Centers
- Enterprise IT
- OEM Workstations
- Government and Defense
- Other End-user Industries
- By Geography
- North America
- Europe
- Asia-Pacific
- China
- Japan
- South Korea
- Taiwan
- Rest of Asia-Pacific
- Rest of the World
Geography Analysis
North America accounted for 45.9% of the GDDR7 market share for the AI inference GPU market in 2025, making it the largest regional contributor. The region benefits from the concentration of hyperscale cloud operators, AI chip designers, and enterprise hardware buyers in the United States. It also has strong pull-through from platform operators that can quickly commercialize new inference infrastructure. AWS showed that in January 2026, with its EC2 G7e launch, which brought GDDR7-based inference capacity into a broad enterprise cloud offering. North America also shapes the product roadmap because many system-level decisions by GPU architects, cloud companies, and enterprise software stacks begin there.
Europe represents a smaller but stable part of the GDDR7 for AI inference GPU market, supported by enterprise AI adoption, industrial automation, and public sector interest in more controlled compute environments. The region is well-suited to workstation and appliance deployments where privacy, data handling, and local control matter. Defense demand is also becoming more visible, especially in ruggedized and embedded compute formats. Kontron's July 2026 launch of the VX33211 for defense and aerospace AI inference reflects that shift toward mission-ready edge platforms. These factors give Europe a measured growth path rather than a sudden volume surge.
Asia-Pacific is the fastest-growing region, with a 43% CAGR through 2031, and it stands out because it combines production leadership with rising end-user demand. Samsung and SK hynix give the region major supply-side weight, while China, Japan, South Korea, and Taiwan add important demand and integration roles. Reuters reported that NVIDIA's China-focused Blackwell product would use GDDR7 instead of HBM, which shows how policy and regional access conditions are reshaping hardware design in Asia. Micron also positioned GDDR7 for AI PC and hybrid compute workflows in Japan, which points to widening enterprise demand beyond cloud infrastructure alone. Rest of the World remains smaller today, but sovereign AI investment and expanding cloud infrastructure could lift its role later in the forecast period.
- Samsung Electronics Co., Ltd.
- SK hynix Inc.
- Micron Technology, Inc.
- NVIDIA Corporation
- Advanced Micro Devices, Inc.
- Rambus Inc.
- TSMC
- Intel Corporation
- Synopsys, Inc.
- Cadence Design Systems, Inc.
Additional Benefits:
- The market estimate (ME) sheet in Excel format
- 3 months of analyst support
TABLE OF CONTENTS
1 INTRODUCTION
- 1.1 Study Assumptions and Market Definition
- 1.2 Scope of The Study
2 RESEARCH METHODOLOGY
3 EXECUTIVE SUMMARY
4 MARKET LANDSCAPE
- 4.1 Market Overview
- 4.2 Market Drivers
- 4.2.1 AI Inference Throughput Gains over HBM in Cost-Sensitive Deployments
- 4.2.2 Power-Efficient Bandwidth Scaling with PAM3 Signaling
- 4.2.3 Rapid Adoption in AI Workstations and Edge Servers
- 4.2.4 GDDR7 Design Wins in Premium GPU Launch Cycles
- 4.2.5 Supplier Qualification Progress for 24 Gb and 32 Gb Dies
- 4.2.6 Localized Inference Demand from Enterprise and Sovereign AI Programs
- 4.3 Market Restraints
- 4.3.1 HBM Preference in Large-Scale Training and Bandwidth-Hungry Inference
- 4.3.2 Limited Leading-Edge DRAM Capacity and Allocation Discipline
- 4.3.3 Thermal and Board-Level Integration Limits in Compact Accelerators
- 4.3.4 Qualification Friction Across GPU, Memory Controller, and Board Designs
- 4.4 Industry Value Chain Analysis
- 4.5 Regulatory Landscape
- 4.6 Technological Outlook
- 4.7 Porter's Five Forces Analysis
- 4.7.1 Bargaining Power of Suppliers
- 4.7.2 Bargaining Power of Buyers
- 4.7.3 Threat of New Entrants
- 4.7.4 Threat of Substitutes
- 4.7.5 Intensity of Competitive Rivalry
- 4.8 Impact of Macroeconomic Factors on the Market
5 MARKET SIZE AND GROWTH FORECASTS (VALUE)
- 5.1 By Memory Density
- 5.1.1 16 Gb
- 5.1.2 24 Gb
- 5.1.3 32 Gb and Above
- 5.2 By Memory Data Rate
- 5.2.1 Up To 32 Gbps
- 5.2.2 Above 32 Gbps
- 5.3 By Application
- 5.3.1 Data Center AI Inference
- 5.3.2 Edge AI Inference
- 5.3.3 Workstation AI
- 5.3.4 Consumer AI Acceleration
- 5.4 By End-User Industry
- 5.4.1 Cloud and Hyperscale Data Centers
- 5.4.2 Enterprise IT
- 5.4.3 OEM Workstations
- 5.4.4 Government and Defense
- 5.4.5 Other End-user Industries
- 5.5 By Geography
- 5.5.1 North America
- 5.5.2 Europe
- 5.5.3 Asia-Pacific
- 5.5.3.1 China
- 5.5.3.2 Japan
- 5.5.3.3 South Korea
- 5.5.3.4 Taiwan
- 5.5.3.5 Rest of Asia-Pacific
- 5.5.4 Rest of the World
6 COMPETITIVE LANDSCAPE
- 6.1 Market Concentration
- 6.2 Strategic Moves
- 6.3 Market Share Analysis
- 6.4 Company Profiles (includes Global Level Overview, Market Level Overview, Core Segments, Financials as available, Strategic Information, Market Rank/Share, Products and Services, Recent Developments)
- 6.4.1 Samsung Electronics Co., Ltd.
- 6.4.2 SK hynix Inc.
- 6.4.3 Micron Technology, Inc.
- 6.4.4 NVIDIA Corporation
- 6.4.5 Advanced Micro Devices, Inc.
- 6.4.6 Rambus Inc.
- 6.4.7 TSMC
- 6.4.8 Intel Corporation
- 6.4.9 Synopsys, Inc.
- 6.4.10 Cadence Design Systems, Inc.
7 MARKET OPPORTUNITIES AND FUTURE OUTLOOK
- 7.1 White-Space And Unmet-Need Assessment

 ESG資料智慧平台市場預測至2034年-按智慧類型、資料來源、分析技術、部署模式、最終使用者和地區分類的全球分析語意層市場預測至 2034 年—按元件、部署模式、架構、資料來源、應用、最終使用者和區域分類的全球分析
 AI加速器DRAM市佔率分析、產業趨勢與統計及成長預測(2026-2031年)
 克服記憶體瓶頸:CXL擴展和KV快取壓縮創新HBM3E:市場佔有率分析、產業趨勢與統計、成長預測(2026-2031)以人工智慧工作負載的 CXL 記憶體擴展:市場佔有率分析、行業趨勢與統計數據以及成長預測(2026-2031 年)衛星資料分析市場預測至2034年-按分析方法、資料類型、部署方式、應用、最終用戶和地區分類的全球分析HBM3:市場佔有率分析、產業趨勢與統計、成長預測(2026-2031)
 2026年全球合成電子健康紀錄(EHR)資料產生平台市場報告人工智慧開發工具市場預測——全球分析(按組件、工具類型、部署模式、組織規模、技術、應用、最終用戶和地區分類)——2034年